Your local language model is waiting on memory, and one command will prove it
Text generation on a CPU is a memory problem wearing a compute problem's clothes. Here is the one-line rule that predicts it, the evidence from seven models on one laptop, and a tool that measures it on your machine.
There is a moment when you first run a language model on your own machine and it is slower than you hoped. My instinct was to reach for the processor: more threads, a higher clock, a build with better compiler flags. I spent about a week on that and got very little for it.
The reason is simple once you see it, and it has almost nothing to do with the processor.
When one of these models writes a word, it reads every one of its weights out of memory to do it. All of them, for one word, and then all of them again for the next word. Nothing is saved, nothing is reused. A model that occupies four gigabytes moves four gigabytes of data per word.
So the speed you get is not really a question about arithmetic. It is a question about how fast your memory can hand over four gigabytes, which is a number your machine has and cannot exceed.
words per second = memory bandwidth / model sizeThat is the whole model. It is close to embarrassing how well it works.
What the fit is actually saying
Seven different models. Different architectures, different quantizations, sizes spanning a factor of fourteen. One line through all of them, and the line has one free parameter, which is the bandwidth.
If arithmetic were the limit, this plot would be a mess. Models with different shapes do wildly different amounts of arithmetic per byte. They land on the same line anyway, because the arithmetic finishes long before the data arrives, and what you are watching is the data arriving.
On this laptop the models sustain about 37.65 gigabytes per second. The machine’s raw memory read speed, measured separately, is 53.9. So generation is running at around 70 percent of the physical ceiling, which is high enough that there is not much software left to win.
I checked the same thing on a Raspberry Pi 5, a machine with roughly a quarter of the memory bandwidth. Same law, same quality of fit, different constant. That is the part that convinced me the rule is about the hardware and not about llama.cpp.
The practical consequences are unromantic
Model size is the dial. Halving the bytes roughly doubles the speed. There is no configuration change that competes with this, which is why quantization is the lever everybody actually pulls, whether or not they know why.
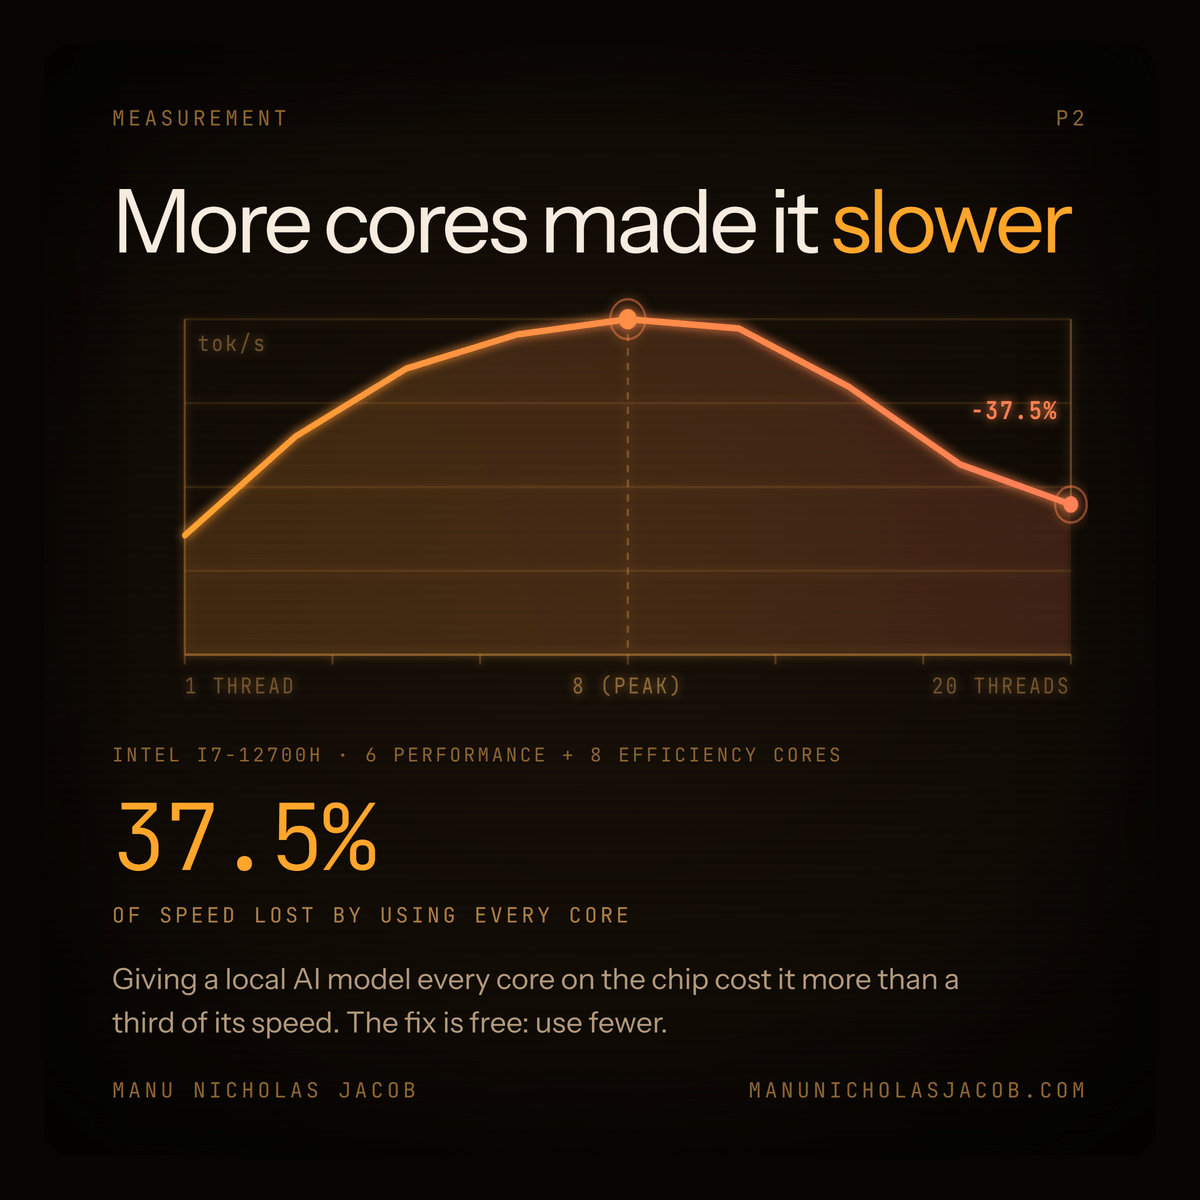
More threads stop helping early. Once the memory is saturated, extra cores queue for it. This laptop has six fast cores and eight slow ones, and generation peaks near the fast-core count. Running all twenty threads, which pulls the slow cores in, cost the smallest model 37 percent of its peak. Prompt processing, which is genuinely compute-bound, kept scaling the whole way to twenty. The two halves of the same workload want different thread counts, and the usual advice to just use every core gets one of them wrong.
A faster clock buys very little. A stalled core stalls faster.
You can size a model for a target speed before you download it. Take your machine’s bandwidth, divide by the speed you want, and that is your byte budget.
Measuring it on your machine
I wrote a tool for this because I got tired of doing it by hand.
pip install llama-roofline
llama-roofline run --models ~/models/*.gguf
It finds your llama-bench, measures your actual sustainable memory bandwidth
with a read kernel rather than trusting a spec sheet, sweeps thread counts, fits
the line, and then prints a report card in English that tells you whether your
decode is memory-bound and what to do about it. On the laptop above it takes
about half an hour, most of which is benchmarking models.
The code is on GitHub and archived at 10.5281/zenodo.21842493. Both example report cards in the repository are real runs, not illustrations.
The thing I would most like is a report card from a machine with a memory system I cannot get at. Apple Silicon, a server with eight memory channels, anything where the ratio between compute and bandwidth is somewhere other than where mine sits. If the line bends on your hardware, that is more interesting than all seven of my points.
Written by